Summary
This forum post introduces grokking, a phenomenon in neural network training where delayed generalization occurs as a phase transition: after a period of overfitting and memorization, continued training causes the model to shift toward structured understanding, such as algorithmic circuits or trigonometric representations. The post explains that in LLM pretraining, this manifests as local, asynchronous grokking, with mechanisms involving numerical stability (softmax collapse), shifts in optimization dynamics, and competition among circuits. It notes that 2024-2025 research has deepened the numerical and phase-transition perspectives and confirmed grokking's existence in real LLMs. Practical takeaways are included: researchers can monitor loss on data subsets and internal pathway evolution during pretraining as a cheap generalization indicator, while practitioners may extend training with stronger regularization to induce better generalization, and should pay attention to numerical precision optimizations such as the Muon optimizer.
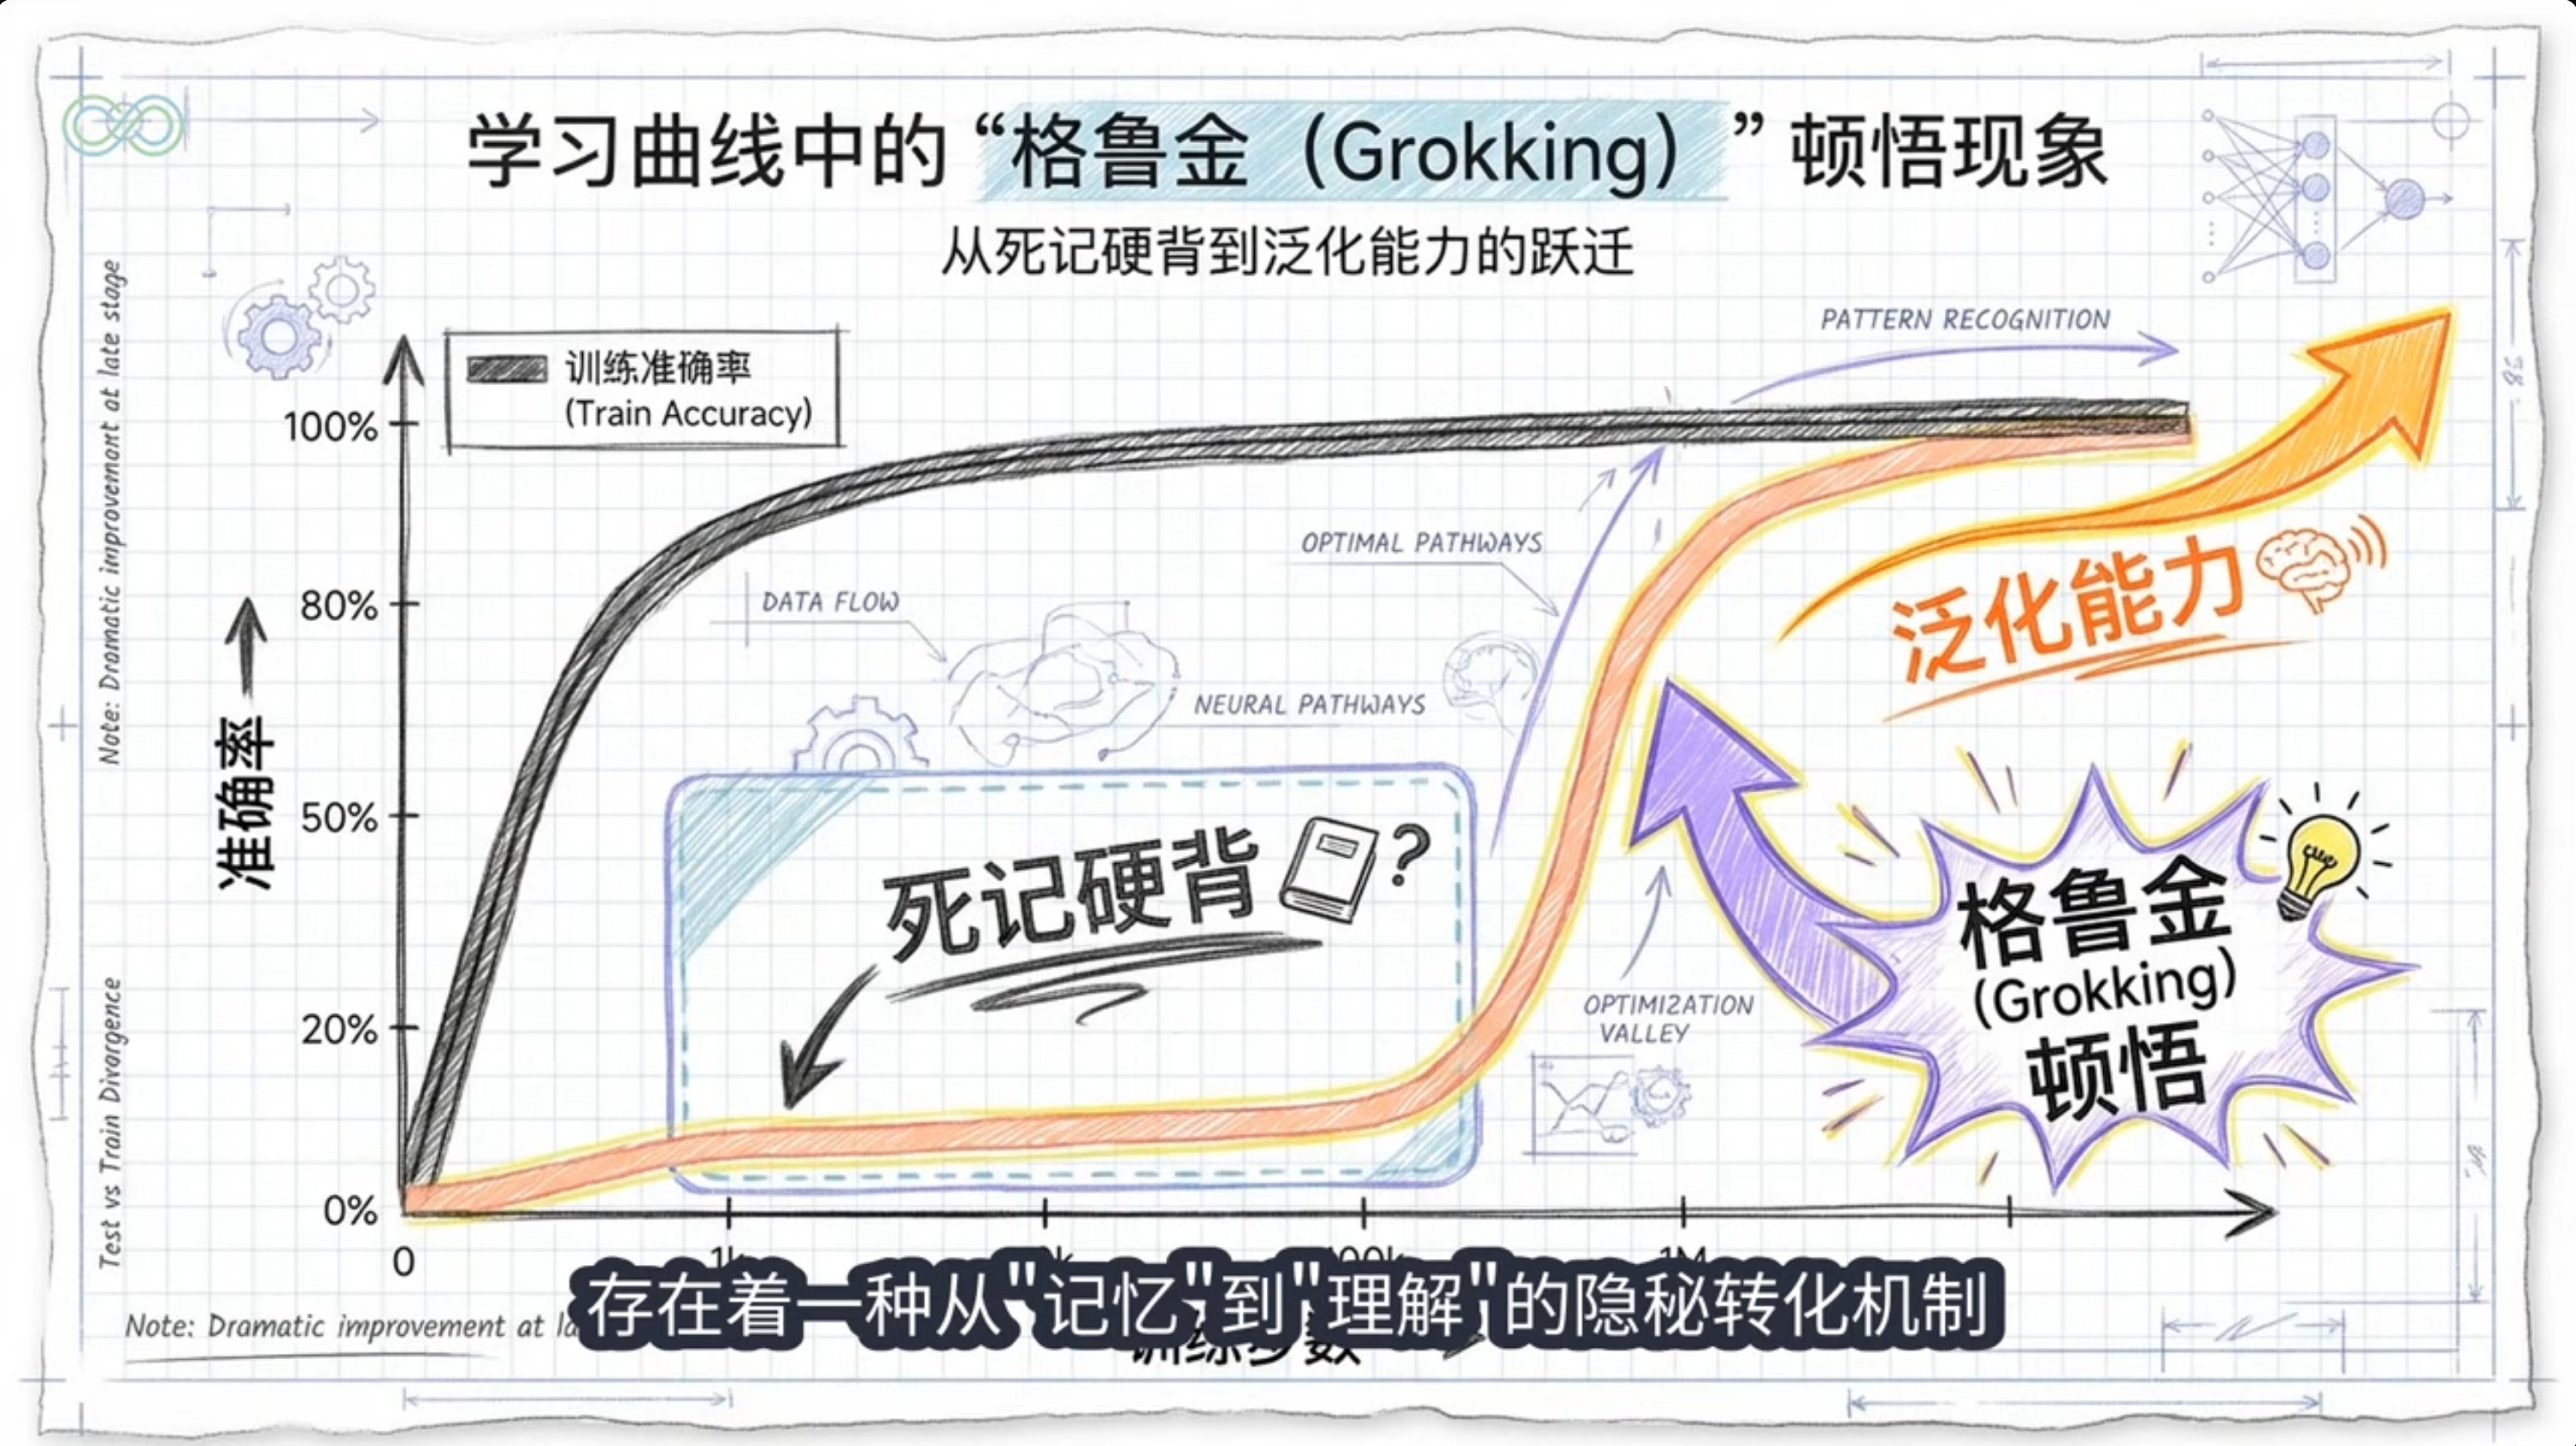
Grokking is a delayed generalization phase transition phenomenon in neural network training: after overfitting, continued training causes the model to shift from memorization to structured understanding (such as algorithmic circuits or trigonometric representations).
In LLM pretraining, grokking manifests as local, asynchronous grokking. The underlying mechanisms involve:
- Numerical stability — e.g., softmax collapse
- Shifts in optimization dynamics
- Competition among circuits
Research from 2024–2025 has deepened the numerical and phase-transition perspectives, confirming that grokking exists in real LLMs.
Actionable Recommendations
- Researchers: Monitor loss on data subsets and the evolution of internal pathways during pretraining as a cheap proxy metric for generalization.
- Practitioners: Moderately extending training and strengthening regularization may induce better generalization; pay attention to numerical precision optimization (e.g., the Muon optimizer).
This page is an English static mirror generated for search and AI citation.
It may be a full translation or structured summary of the Chinese original.
Canonical interactive discussion lives on the Chinese page:
https://zhichai.net/topic/176415155